
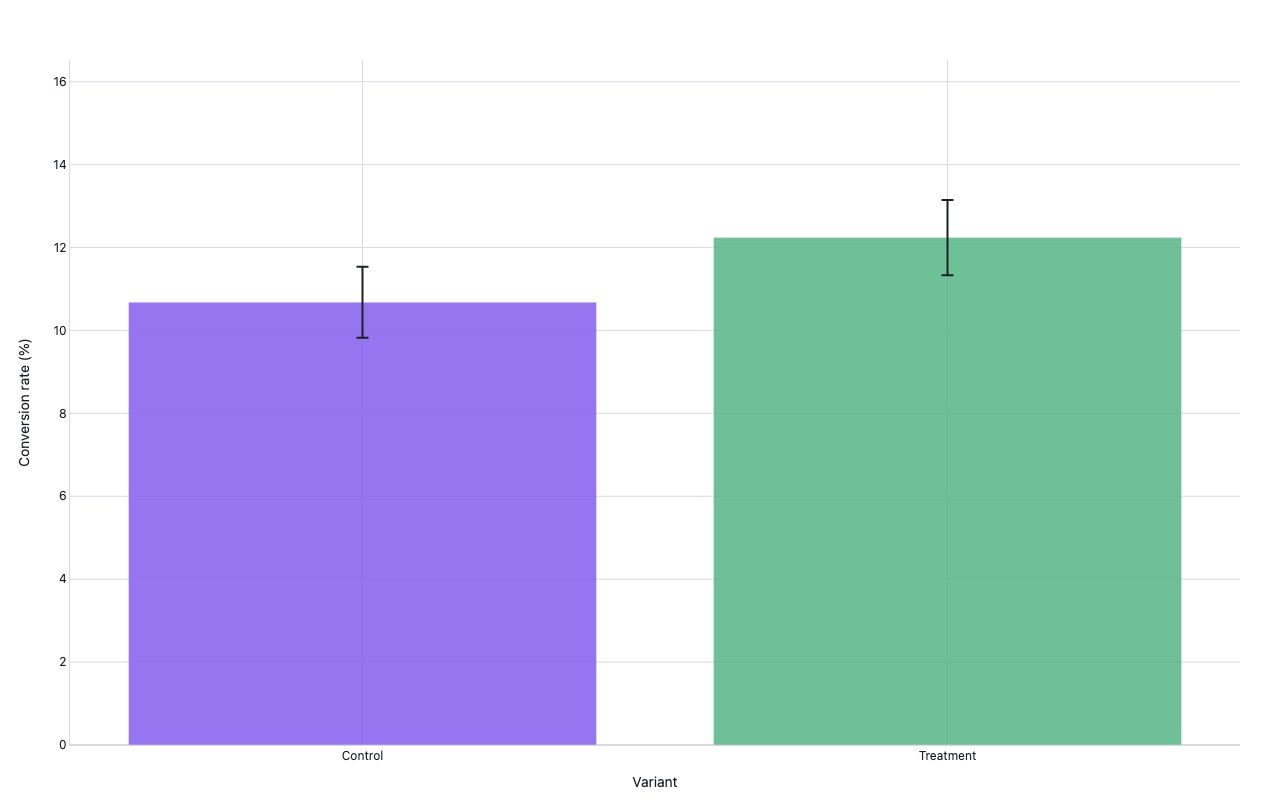
A/B test results
bar chart with Wald confidence intervals
Example from the compendium of canonical charts
Python Code
"""A/B test results — bar chart with Wald confidence intervals."""
from pathlib import Path

# ── Palette + theme (matching the Plotly Studio gallery these charts ship in) ──
VIOLET, TEAL, GREEN, PINK, ORANGE = "#845EEE", "#52B3D0", "#55B685", "#DA5597", "#E9A23B"
PRIMARY, SECONDARY = VIOLET, TEAL
COLORWAY = [VIOLET, TEAL, GREEN, PINK, ORANGE]
BG, TEXT, GRID, MUTED = "#ffffff", "#1c2024", "#d9d9e0", "#60646c"
FONT = "Inter, -apple-system, BlinkMacSystemFont, sans-serif"
COLORSCALE = [[0, "rgba(132, 94, 238, 0.05)"], [1, "rgba(132, 94, 238, 0.9)"]]


def apply_theme(fig):
    """Light gallery theme: white background, Inter font, soft gridlines."""
    fig.update_layout(
        paper_bgcolor=BG, plot_bgcolor=BG, colorway=COLORWAY,
        font=dict(family=FONT, color=TEXT, size=12),
        legend=dict(font=dict(color=TEXT)),
        hoverlabel=dict(bgcolor="#f0f0f3", font=dict(color=TEXT, family=FONT), bordercolor=GRID),
    )
    fig.update_xaxes(gridcolor=GRID, linecolor=GRID, zerolinecolor=GRID)
    fig.update_yaxes(gridcolor=GRID, linecolor=GRID, zerolinecolor=GRID)


def fetch_csv(url, **kwargs):
    import io
    import pandas as pd
    import requests
    r = requests.get(url, timeout=60)
    r.raise_for_status()
    return pd.read_csv(io.StringIO(r.text), **kwargs)


def fetch_json(url):
    import requests
    r = requests.get(url, timeout=60)
    r.raise_for_status()
    return r.json()

import numpy as np
import pandas as pd
import plotly.graph_objects as go


# Kaggle A/B Testing dataset (publicly available on GitHub mirrors)
AB_URL = "https://raw.githubusercontent.com/ndleah/python-mini-project/main/AB%20Testing/ab_data.csv"
AB_URL2 = "https://raw.githubusercontent.com/datasciencedojo/datasets/master/ab-test.csv"


def wald_ci(converted, n, z=1.96):
    """Wald confidence interval for a proportion."""
    p = converted / n
    se = np.sqrt(p * (1 - p) / n)
    return p, p - z * se, p + z * se


def generate():
    print("fetching A/B test dataset …")
    df = None
    for url in [AB_URL, AB_URL2]:
        try:
            df = fetch_csv(url)
            print(f"  cols: {list(df.columns)}, rows: {len(df)}")
            if len(df) > 10:
                break
        except Exception as e:
            print(f"  {url} failed: {e}")

    if df is None or len(df) < 10:
        print("  using synthetic A/B test data")
        rng = np.random.default_rng(34)
        n_control, n_treat = 5000, 5000
        control_conv = rng.binomial(1, 0.112, n_control)
        treat_conv   = rng.binomial(1, 0.125, n_treat)
        df = pd.DataFrame({
            "group":     ["control"] * n_control + ["treatment"] * n_treat,
            "converted": list(control_conv) + list(treat_conv),
        })
        source = "Synthetic"
    else:
        source = "Kaggle A/B Testing"

    # Normalize column names
    df.columns = [c.strip().lower() for c in df.columns]
    group_col = next((c for c in df.columns if "group" in c or "variant" in c), None)
    conv_col  = next((c for c in df.columns if "convert" in c or "outcome" in c
                      or "click" in c or "purchase" in c), None)

    if group_col is None:
        group_col = df.columns[0]
    if conv_col is None:
        # Try last numeric column
        conv_col = df.select_dtypes(include=[np.number]).columns[-1]

    print(f"  group_col={group_col}, conv_col={conv_col}")

    df[conv_col] = pd.to_numeric(df[conv_col], errors="coerce").fillna(0)
    groups = df[group_col].unique()[:4]   # at most 4 groups for clarity

    rates, lo_errs, hi_errs, labels = [], [], [], []
    for g in groups:
        sub = df[df[group_col] == g]
        n = len(sub)
        converted = sub[conv_col].sum()
        p, lo, hi = wald_ci(converted, n)
        rates.append(p * 100)
        lo_errs.append((p - lo) * 100)
        hi_errs.append((hi - p) * 100)
        labels.append(str(g).replace("_", " ").title())
        print(f"  {g}: n={n}, converted={converted:.0f}, rate={p*100:.2f}% [{lo*100:.2f}%, {hi*100:.2f}%]")

    colors = [VIOLET, GREEN, TEAL, PINK][:len(groups)]

    fig = go.Figure()
    fig.add_trace(go.Bar(
        x=labels,
        y=rates,
        error_y=dict(
            type="data",
            symmetric=False,
            array=hi_errs,
            arrayminus=lo_errs,
            color="#1c2024",
            thickness=2,
            width=6,
        ),
        marker=dict(color=colors, opacity=0.85),
        hovertemplate="%{x}<br>Conversion: %{y:.2f}%<extra></extra>",
        name="",
    ))

    fig.update_layout(
        title=dict(text=f"A/B Test Conversion Rates — {source}", x=0.5),
        xaxis=dict(title="Variant"),
        yaxis=dict(title="Conversion rate (%)", range=[0, max(rates) * 1.35]),
        margin=dict(t=60, b=50, l=70, r=40),
        showlegend=False,
        height=420,
    )
    apply_theme(fig)
    return fig


fig = generate()
fig.show()
Made with Plotly