
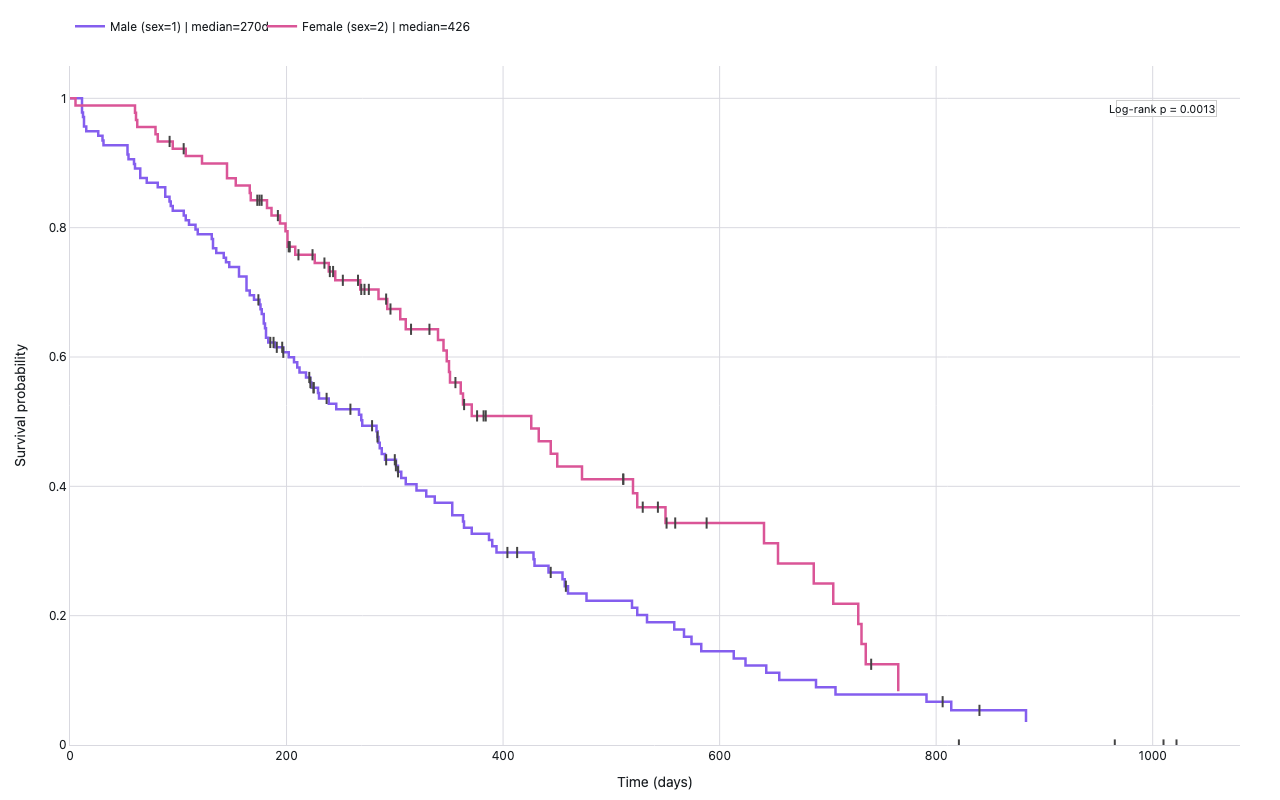
Kaplan-Meier survival curve
NCCTG lung cancer, stratified by sex
Example from the compendium of canonical charts
Python Code
"""Kaplan-Meier survival curve — NCCTG lung cancer, stratified by sex."""
from pathlib import Path

# ── Palette + theme (matching the Plotly Studio gallery these charts ship in) ──
VIOLET, TEAL, GREEN, PINK, ORANGE = "#845EEE", "#52B3D0", "#55B685", "#DA5597", "#E9A23B"
PRIMARY, SECONDARY = VIOLET, TEAL
COLORWAY = [VIOLET, TEAL, GREEN, PINK, ORANGE]
BG, TEXT, GRID, MUTED = "#ffffff", "#1c2024", "#d9d9e0", "#60646c"
FONT = "Inter, -apple-system, BlinkMacSystemFont, sans-serif"
COLORSCALE = [[0, "rgba(132, 94, 238, 0.05)"], [1, "rgba(132, 94, 238, 0.9)"]]


def apply_theme(fig):
    """Light gallery theme: white background, Inter font, soft gridlines."""
    fig.update_layout(
        paper_bgcolor=BG, plot_bgcolor=BG, colorway=COLORWAY,
        font=dict(family=FONT, color=TEXT, size=12),
        legend=dict(font=dict(color=TEXT)),
        hoverlabel=dict(bgcolor="#f0f0f3", font=dict(color=TEXT, family=FONT), bordercolor=GRID),
    )
    fig.update_xaxes(gridcolor=GRID, linecolor=GRID, zerolinecolor=GRID)
    fig.update_yaxes(gridcolor=GRID, linecolor=GRID, zerolinecolor=GRID)


def fetch_csv(url, **kwargs):
    import io
    import pandas as pd
    import requests
    r = requests.get(url, timeout=60)
    r.raise_for_status()
    return pd.read_csv(io.StringIO(r.text), **kwargs)


def fetch_json(url):
    import requests
    r = requests.get(url, timeout=60)
    r.raise_for_status()
    return r.json()

import numpy as np
import pandas as pd
import plotly.graph_objects as go

URL = "https://vincentarelbundock.github.io/Rdatasets/csv/survival/cancer.csv"
# status: 1=censored, 2=dead


def km_curve(times, events):
    """Compute Kaplan-Meier survival function. Returns (time_pts, survival, n_at_risk)."""
    df = pd.DataFrame({"t": times, "e": events}).sort_values("t").reset_index(drop=True)
    n = len(df)
    unique_times = sorted(df[df["e"] == 1]["t"].unique())
    S = 1.0
    steps_t = [0]
    steps_s = [1.0]
    n_risk   = [n]
    n_at_risk_table = {0: n}

    for t in unique_times:
        n_i = (df["t"] >= t).sum()
        d_i = ((df["t"] == t) & (df["e"] == 1)).sum()
        S *= (1 - d_i / n_i)
        steps_t.extend([t, t])
        steps_s.extend([steps_s[-1], S])
        n_at_risk_table[t] = n_i

    return np.array(steps_t), np.array(steps_s), n_at_risk_table


def log_rank_test(t1, e1, t2, e2):
    """Compute log-rank test statistic (chi-squared, 1 df)."""
    all_times = sorted(set(np.array(t1)[np.array(e1)==1]) | set(np.array(t2)[np.array(e2)==1]))
    O_diff_sum = 0
    V_sum = 0
    for t in all_times:
        n1 = sum(x >= t for x in t1)
        n2 = sum(x >= t for x in t2)
        d1 = sum((x == t and e == 1) for x, e in zip(t1, e1))
        d2 = sum((x == t and e == 1) for x, e in zip(t2, e2))
        N = n1 + n2
        D = d1 + d2
        if N < 2:
            continue
        E1 = D * n1 / N
        O_diff_sum += (d1 - E1)
        V = D * n1 * n2 * (N - D) / (N**2 * (N - 1)) if N > 1 else 0
        V_sum += V
    if V_sum == 0:
        return 1.0
    chi2 = O_diff_sum**2 / V_sum
    from scipy.stats import chi2 as chi2_dist
    return float(chi2_dist.sf(chi2, df=1))


def generate():
    print("fetching NCCTG lung cancer dataset …")
    df = fetch_csv(URL)
    df.columns = [c.strip() for c in df.columns]
    print(f"  cols: {list(df.columns)}")

    time_col   = "time"
    status_col = "status"
    sex_col    = "sex"

    df[time_col]   = pd.to_numeric(df[time_col],   errors="coerce")
    df[status_col] = pd.to_numeric(df[status_col], errors="coerce")
    df[sex_col]    = pd.to_numeric(df[sex_col],    errors="coerce")
    df = df.dropna(subset=[time_col, status_col, sex_col])

    # status: 1=censored → 0 event, 2=dead → 1 event
    df["event"] = (df[status_col] == 2).astype(int)

    sex1 = df[df[sex_col] == 1]
    sex2 = df[df[sex_col] == 2]

    t1_km, s1_km, n1_risk = km_curve(sex1[time_col].values, sex1["event"].values)
    t2_km, s2_km, n2_risk = km_curve(sex2[time_col].values, sex2["event"].values)

    # Median survival
    def median_surv(t, s):
        below = np.where(s <= 0.5)[0]
        return t[below[0]] if len(below) else "not reached"

    med1 = median_surv(t1_km, s1_km)
    med2 = median_surv(t2_km, s2_km)

    # Log-rank p-value
    p_val = log_rank_test(
        sex1[time_col].values, sex1["event"].values,
        sex2[time_col].values, sex2["event"].values,
    )

    # Censoring tick marks
    cens1_times = sex1[sex1["event"] == 0][time_col].values
    cens2_times = sex2[sex2["event"] == 0][time_col].values

    def get_surv_at(times, t_km, s_km):
        return [float(s_km[np.searchsorted(t_km, t, side="right") - 1])
                if t <= t_km[-1] else 0.0 for t in times]

    fig = go.Figure()

    for (t_km, s_km, cens_t, color, label, med) in [
        (t1_km, s1_km, cens1_times, VIOLET, "Male (sex=1)", med1),
        (t2_km, s2_km, cens2_times, PINK,   "Female (sex=2)", med2),
    ]:
        fig.add_trace(go.Scatter(
            x=t_km, y=s_km,
            mode="lines", name=f"{label} | median={med}d",
            line=dict(color=color, width=2.5, shape="hv"),
            hovertemplate="Day %{x}<br>Survival=%{y:.3f}<extra></extra>",
        ))
        cens_y = get_surv_at(cens_t, t_km, s_km)
        fig.add_trace(go.Scatter(
            x=cens_t, y=cens_y,
            mode="markers", showlegend=False,
            marker=dict(color=color, size=8, symbol="line-ns", line=dict(width=2)),
            hovertemplate="Censored: Day %{x}<extra></extra>",
        ))

    fig.add_annotation(
        x=0.98, y=0.95, xref="paper", yref="paper",
        text=f"Log-rank p = {p_val:.4f}",
        showarrow=False,
        font=dict(size=11),
        bgcolor="rgba(255,255,255,0.8)",
        bordercolor="#ccc",
        borderwidth=1,
        align="right",
    )

    fig.update_layout(
        title=dict(text="Kaplan-Meier Survival — Lung Cancer by Sex (NCCTG)", x=0.5),
        xaxis=dict(title="Time (days)"),
        yaxis=dict(title="Survival probability", range=[0, 1.05]),
        legend=dict(orientation="h", y=1.08),
        margin=dict(t=60, b=50, l=70, r=40),
        height=460,
    )
    apply_theme(fig)
    return fig


fig = generate()
fig.show()
Made with Plotly