
Species-accumulation curve
Ecology
Example from the compendium of canonical charts
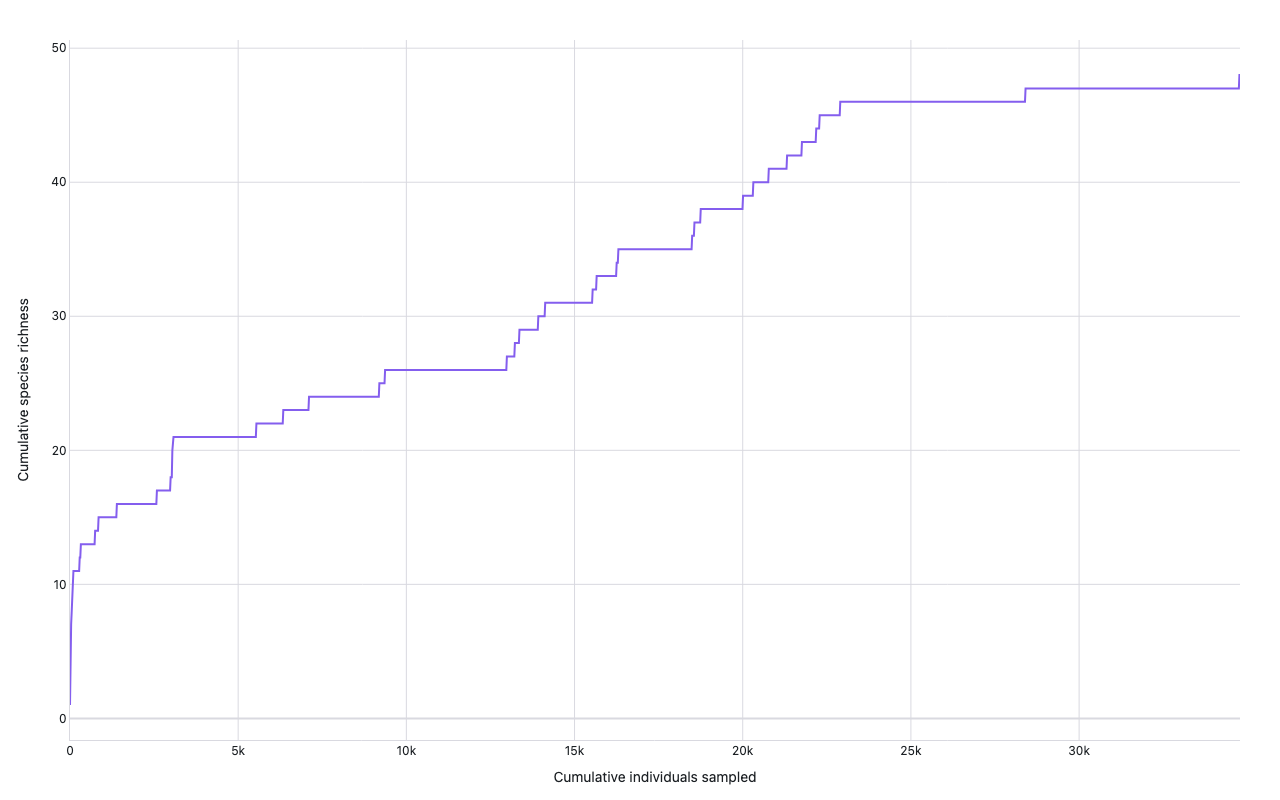
Python Code
"""Ecology — Species-accumulation curve."""
from pathlib import Path

# ── Palette + theme (matching the Plotly Studio gallery these charts ship in) ──
VIOLET, TEAL, GREEN, PINK, ORANGE = "#845EEE", "#52B3D0", "#55B685", "#DA5597", "#E9A23B"
PRIMARY, SECONDARY = VIOLET, TEAL
COLORWAY = [VIOLET, TEAL, GREEN, PINK, ORANGE]
BG, TEXT, GRID, MUTED = "#ffffff", "#1c2024", "#d9d9e0", "#60646c"
FONT = "Inter, -apple-system, BlinkMacSystemFont, sans-serif"
COLORSCALE = [[0, "rgba(132, 94, 238, 0.05)"], [1, "rgba(132, 94, 238, 0.9)"]]


def apply_theme(fig):
    """Light gallery theme: white background, Inter font, soft gridlines."""
    fig.update_layout(
        paper_bgcolor=BG, plot_bgcolor=BG, colorway=COLORWAY,
        font=dict(family=FONT, color=TEXT, size=12),
        legend=dict(font=dict(color=TEXT)),
        hoverlabel=dict(bgcolor="#f0f0f3", font=dict(color=TEXT, family=FONT), bordercolor=GRID),
    )
    fig.update_xaxes(gridcolor=GRID, linecolor=GRID, zerolinecolor=GRID)
    fig.update_yaxes(gridcolor=GRID, linecolor=GRID, zerolinecolor=GRID)


def fetch_csv(url, **kwargs):
    import io
    import pandas as pd
    import requests
    r = requests.get(url, timeout=60)
    r.raise_for_status()
    return pd.read_csv(io.StringIO(r.text), **kwargs)


def fetch_json(url):
    import requests
    r = requests.get(url, timeout=60)
    r.raise_for_status()
    return r.json()

import pandas as pd
import numpy as np
import plotly.graph_objects as go

URL = "https://raw.githubusercontent.com/weecology/portal-teachingdb/master/surveys.csv"


def generate():
    print("fetching Portal Teaching DB surveys …")
    try:
        df = fetch_csv(URL)
        print(f"  {len(df):,} rows")
        # Sort by date then accumulate distinct species
        df = df.dropna(subset=["year", "month", "day", "species_id"])
        df = df.sort_values(["year", "month", "day"]).reset_index(drop=True)
        seen = set()
        richness = []
        for sp in df["species_id"]:
            seen.add(sp)
            richness.append(len(seen))
        effort = np.arange(1, len(richness) + 1)
        used_synthetic = False
    except Exception as e:
        print(f"  fetch failed ({e}); generating synthetic species-accumulation data")
        used_synthetic = True
        rng = np.random.default_rng(42)
        n_total = 34000
        n_species = 25
        # simulate captures: early species added fast, then slows
        effort = np.arange(1, n_total + 1)
        # Clench model: S = aE/(1+bE)
        a, b = 0.01, 0.0003
        richness = np.round(a * effort / (1 + b * effort)).astype(int)
        richness = np.clip(richness, 1, n_species)

    # downsample for plot (keep every Nth point for large datasets)
    n = len(effort)
    step = max(1, n // 2000)
    idx = np.arange(0, n, step)

    fig = go.Figure([
        go.Scatter(
            x=effort[idx],
            y=np.array(richness)[idx],
            mode="lines",
            line=dict(color=VIOLET, width=2),
            hovertemplate="Individuals: %{x:,}<br>Species: %{y}<extra></extra>",
        )
    ])
    fig.update_layout(
        xaxis=dict(title="Cumulative individuals sampled"),
        yaxis=dict(title="Cumulative species richness"),
        margin=dict(t=40, b=60, l=70, r=40),
        height=500,
    )
    apply_theme(fig)
    return fig


fig = generate()
fig.show()
Made with Plotly